The World's Fastest Web Search API for Autonomous AI Agents
Sub-10ms BM25 edge search & instant long-term agent memory across 330+ Anycast cities. Zero cold starts, zero latency drift.
 ultrademon-workspace — 330 Anycast PoPs · Active
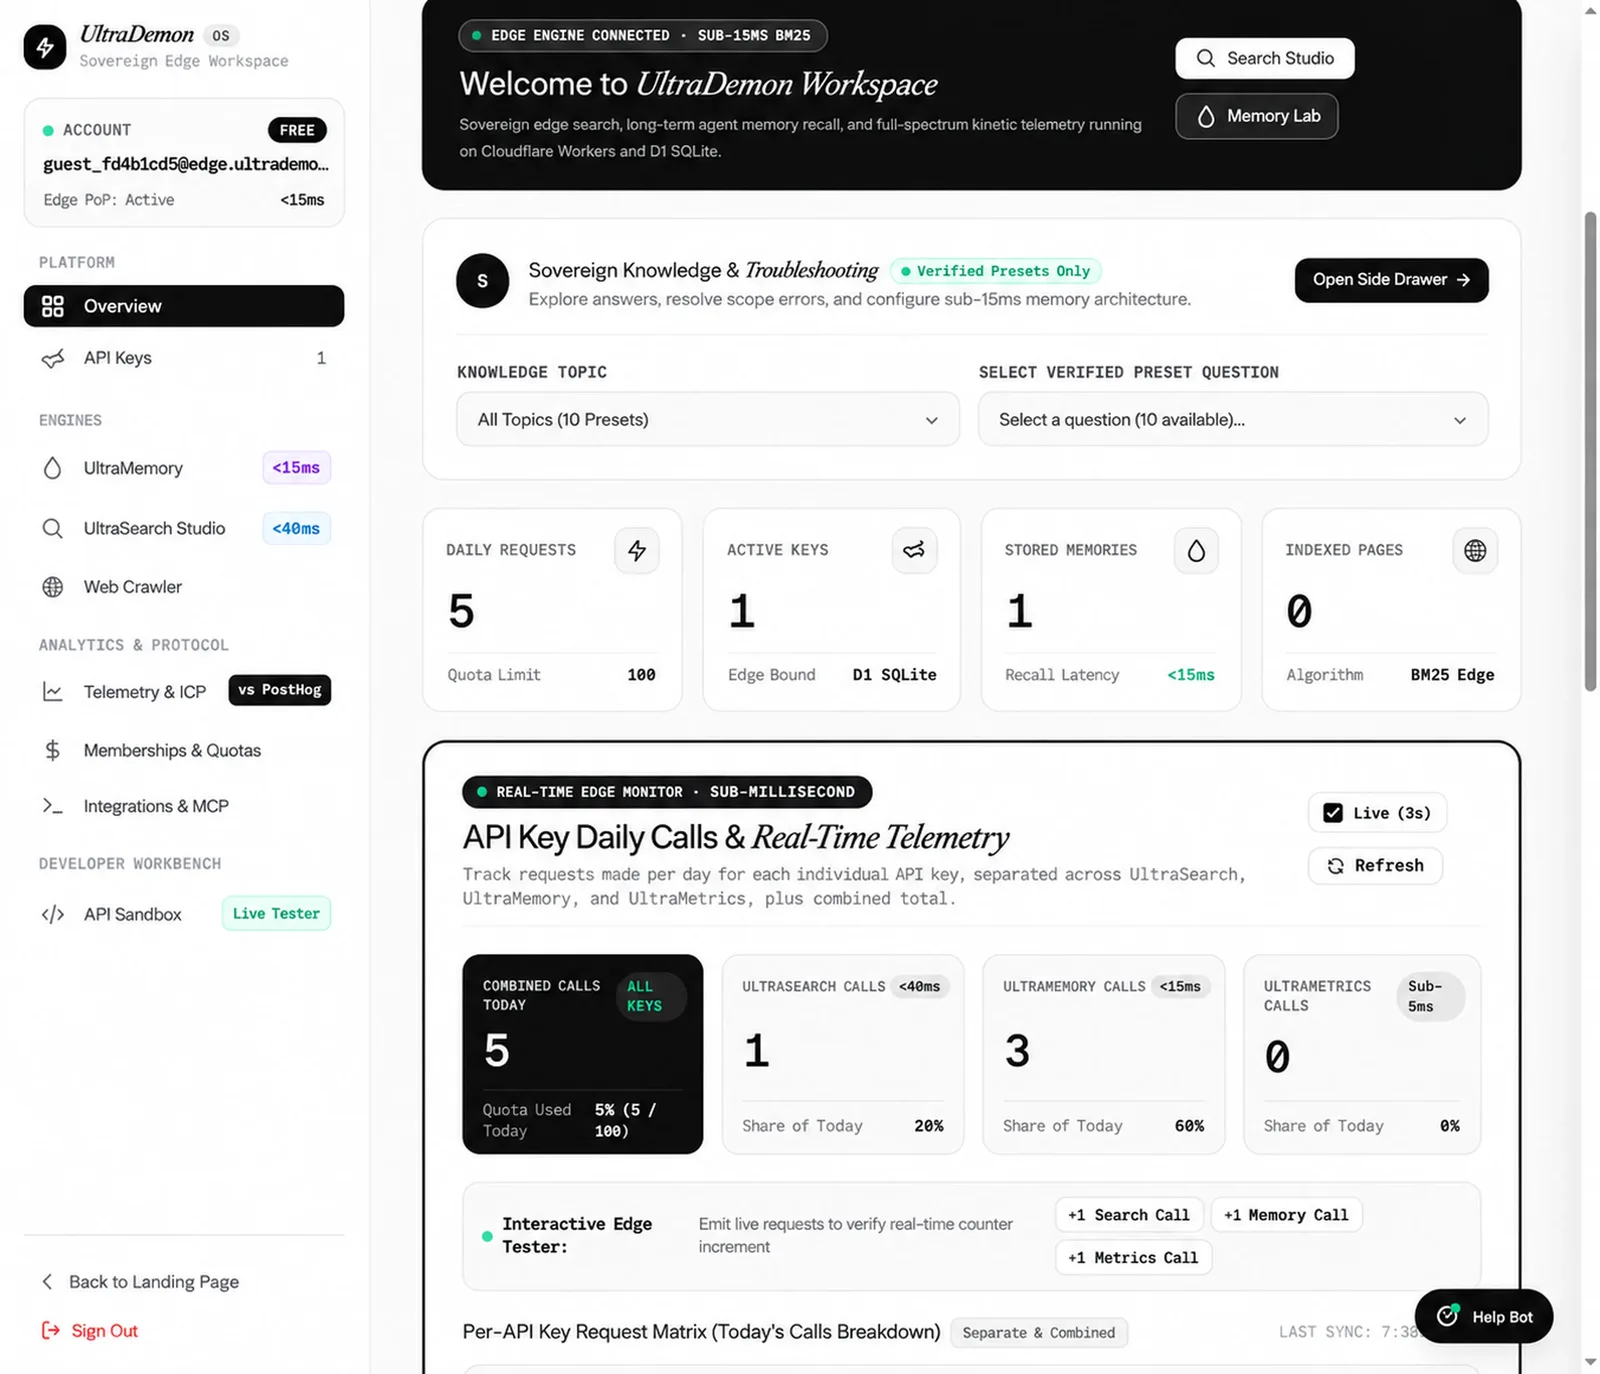
Engineered for agents that refuse third-party latency.
Standard cloud architectures force autonomous agents into multi-region hops, external vector databases, and rate-limited scraper proxies. UltraDemon runs directly inside Cloudflare's Anycast edge across 330+ locations.
Centralized DB & Proxy Bottlenecks
Every memory recall round-trips to us-east-1. Scrapers hit bot blockers and cloud captchas. Swarms spend 80% of runtime waiting on network I/O.
Sovereign Edge In-Memory BM25
Memories, full-text indexes, and search scrapers reside directly in memory at the edge PoP nearest to the client. Zero centralized bottlenecks.
Everything your autonomous agents need to remember and explore
Purpose-built for agent swarms and developer copilots that require sub-15ms memory lookups and sovereign web search without rate limits.
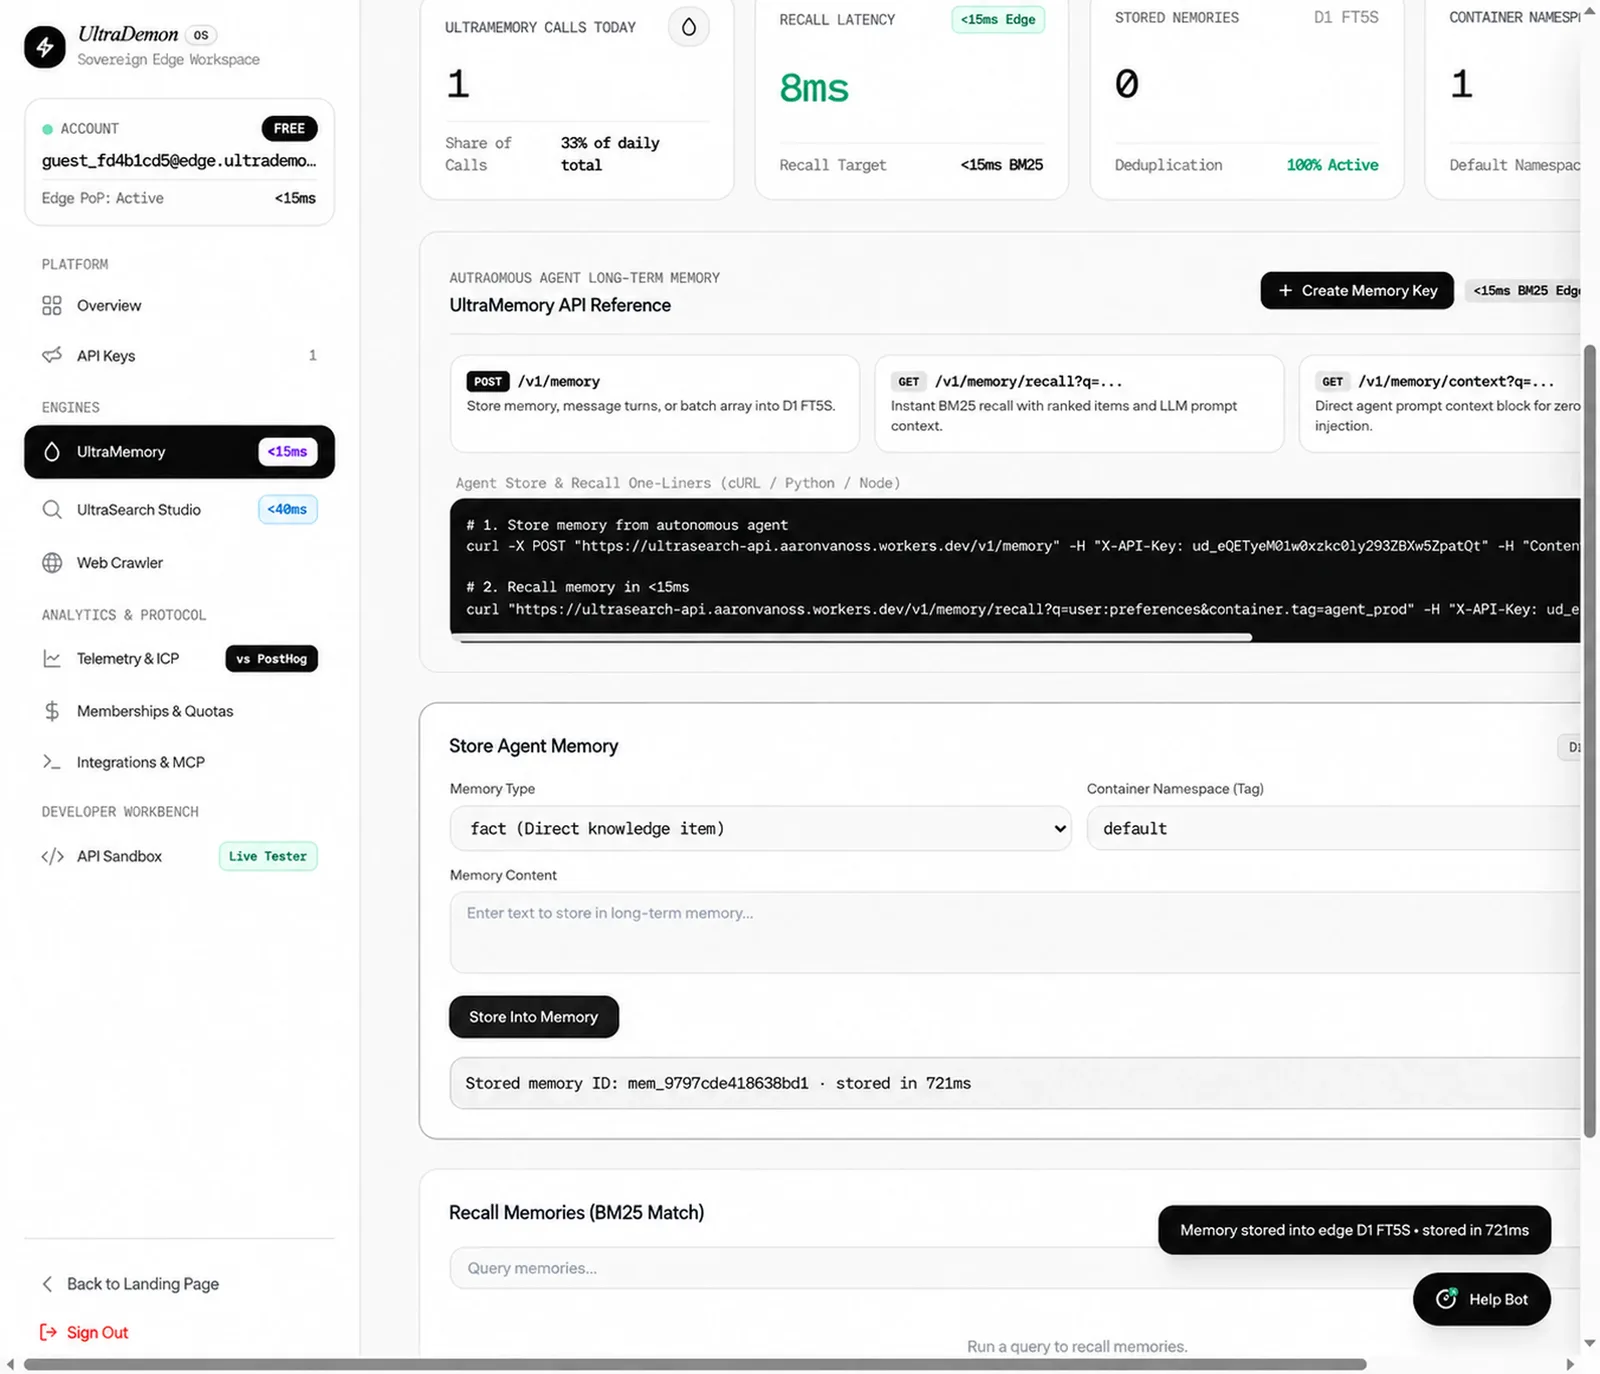
Fastest Memory API: Sub-10ms Long-Term Agent Recall
Structured long-term memory indexed with SQLite FTS5 BM25 directly across 330 Anycast edge locations. Instant associative recall without vector DB drift.
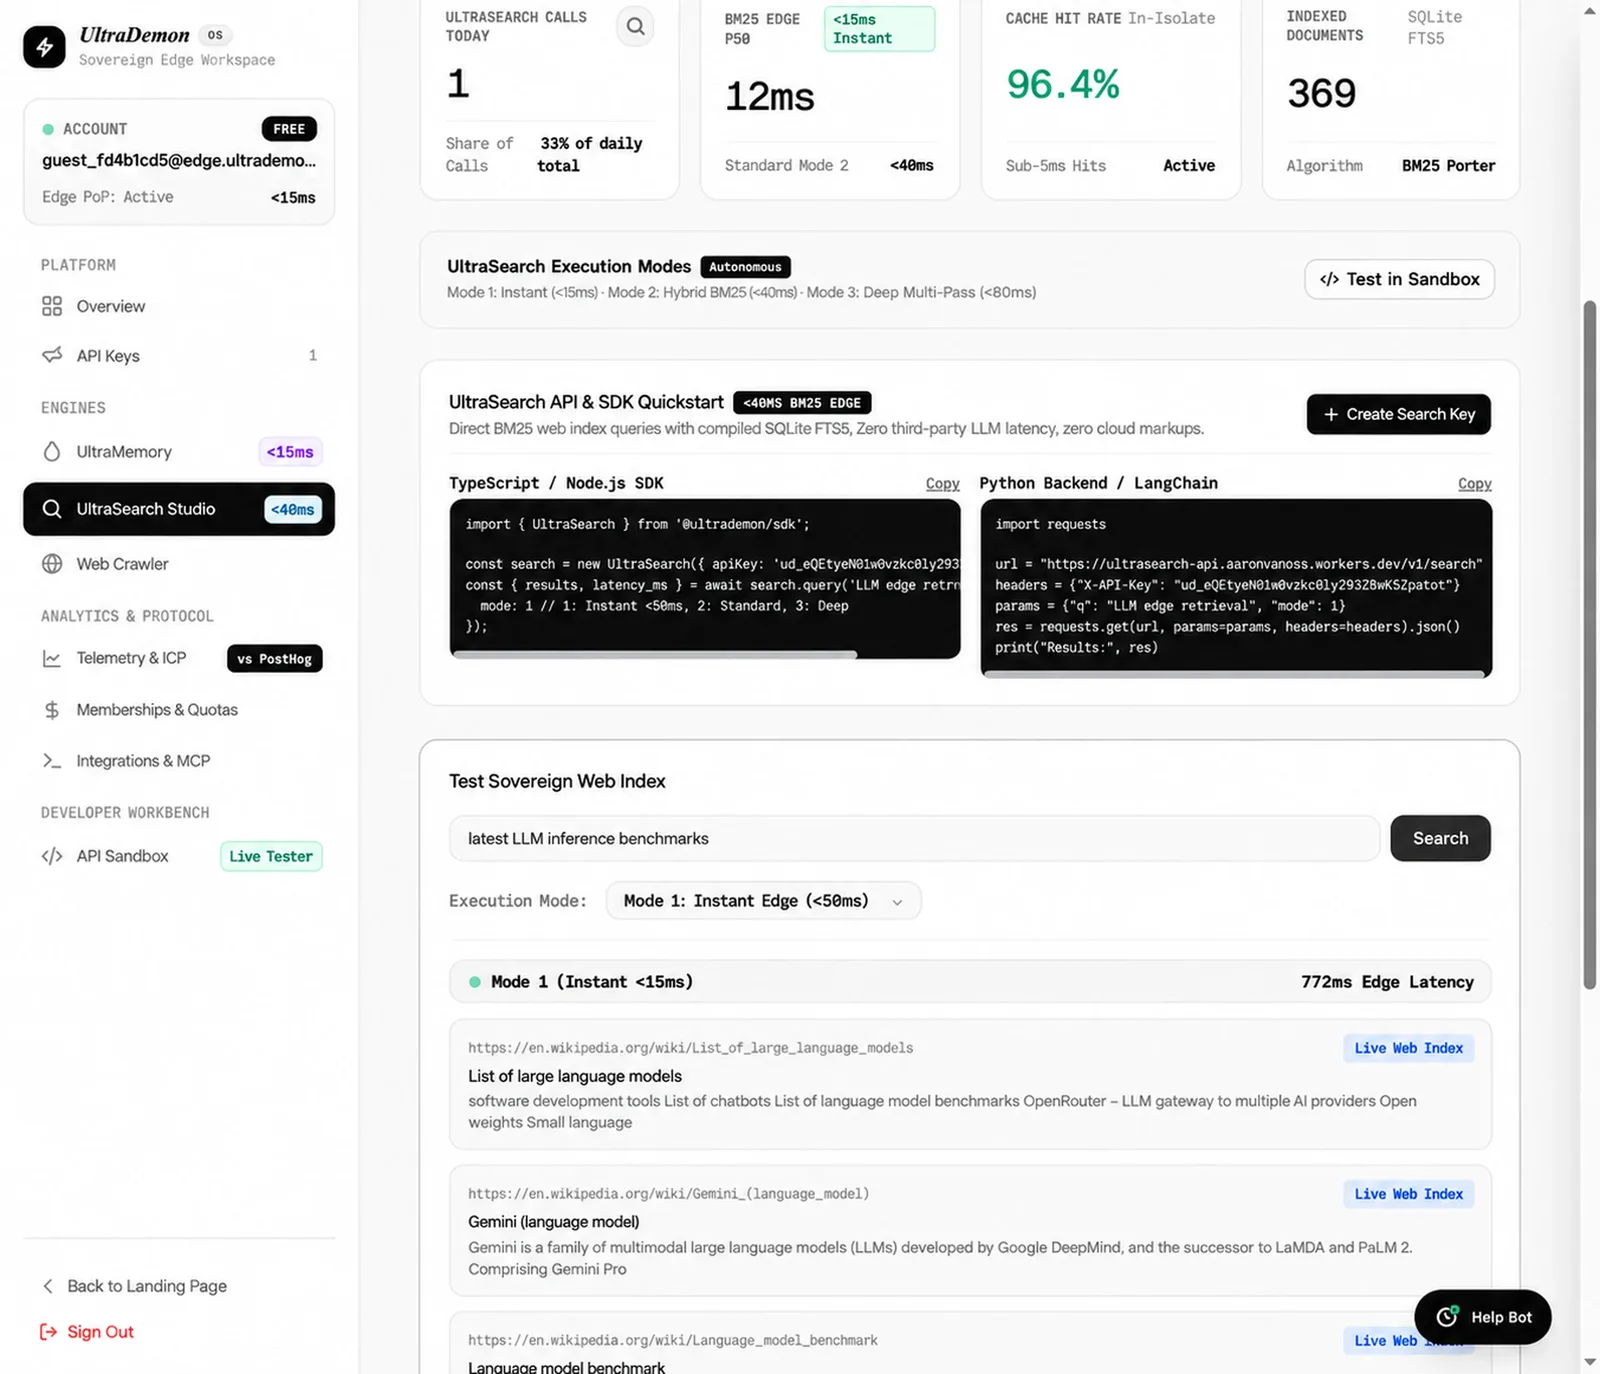
Edge Web Search Studio
Real-time edge web search and autonomous scraping. Scrapes 8 sources simultaneously, parses markdown cleanly, and circumvents anti-bot blocks.
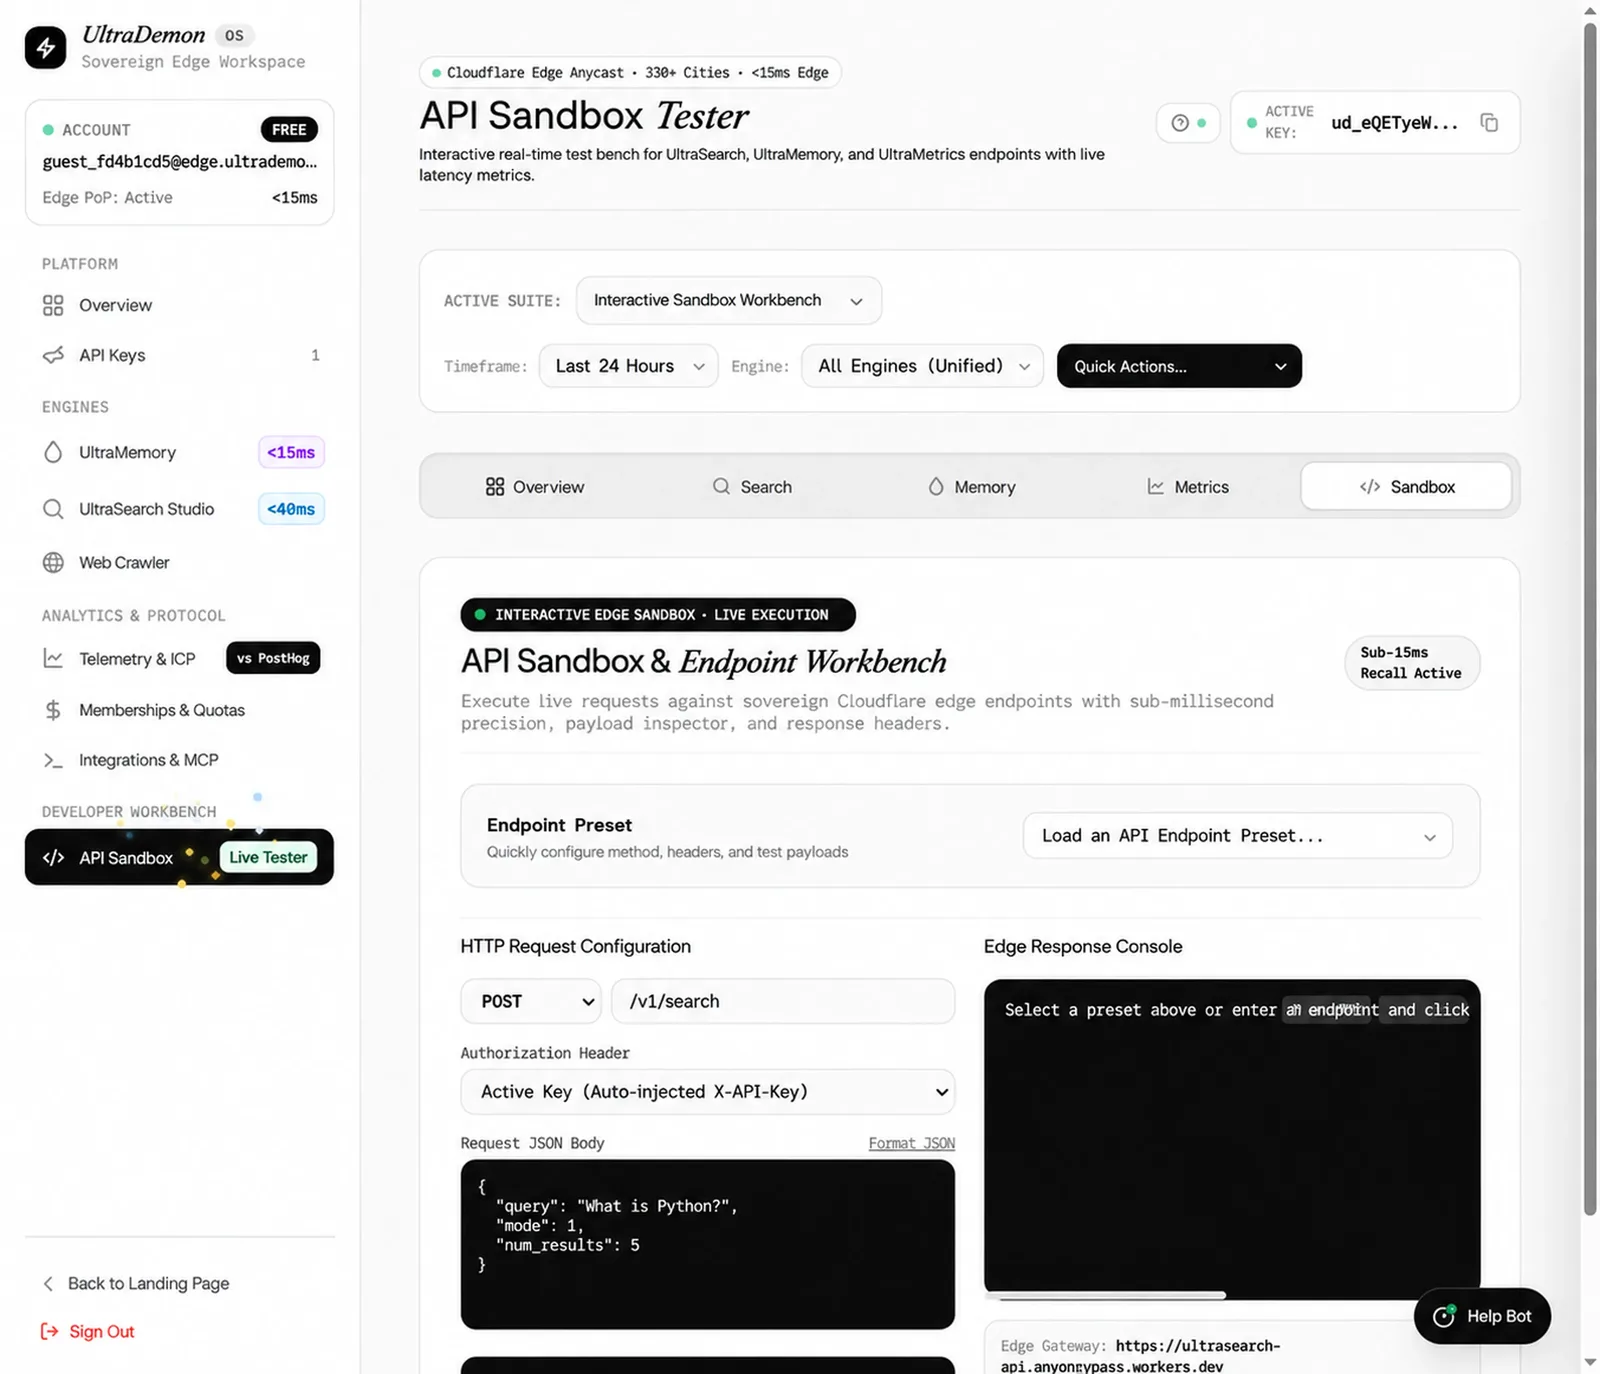
Interactive API Sandbox
Test live endpoints, inspect headers, and calibrate prompt tokens directly in the developer workbench.
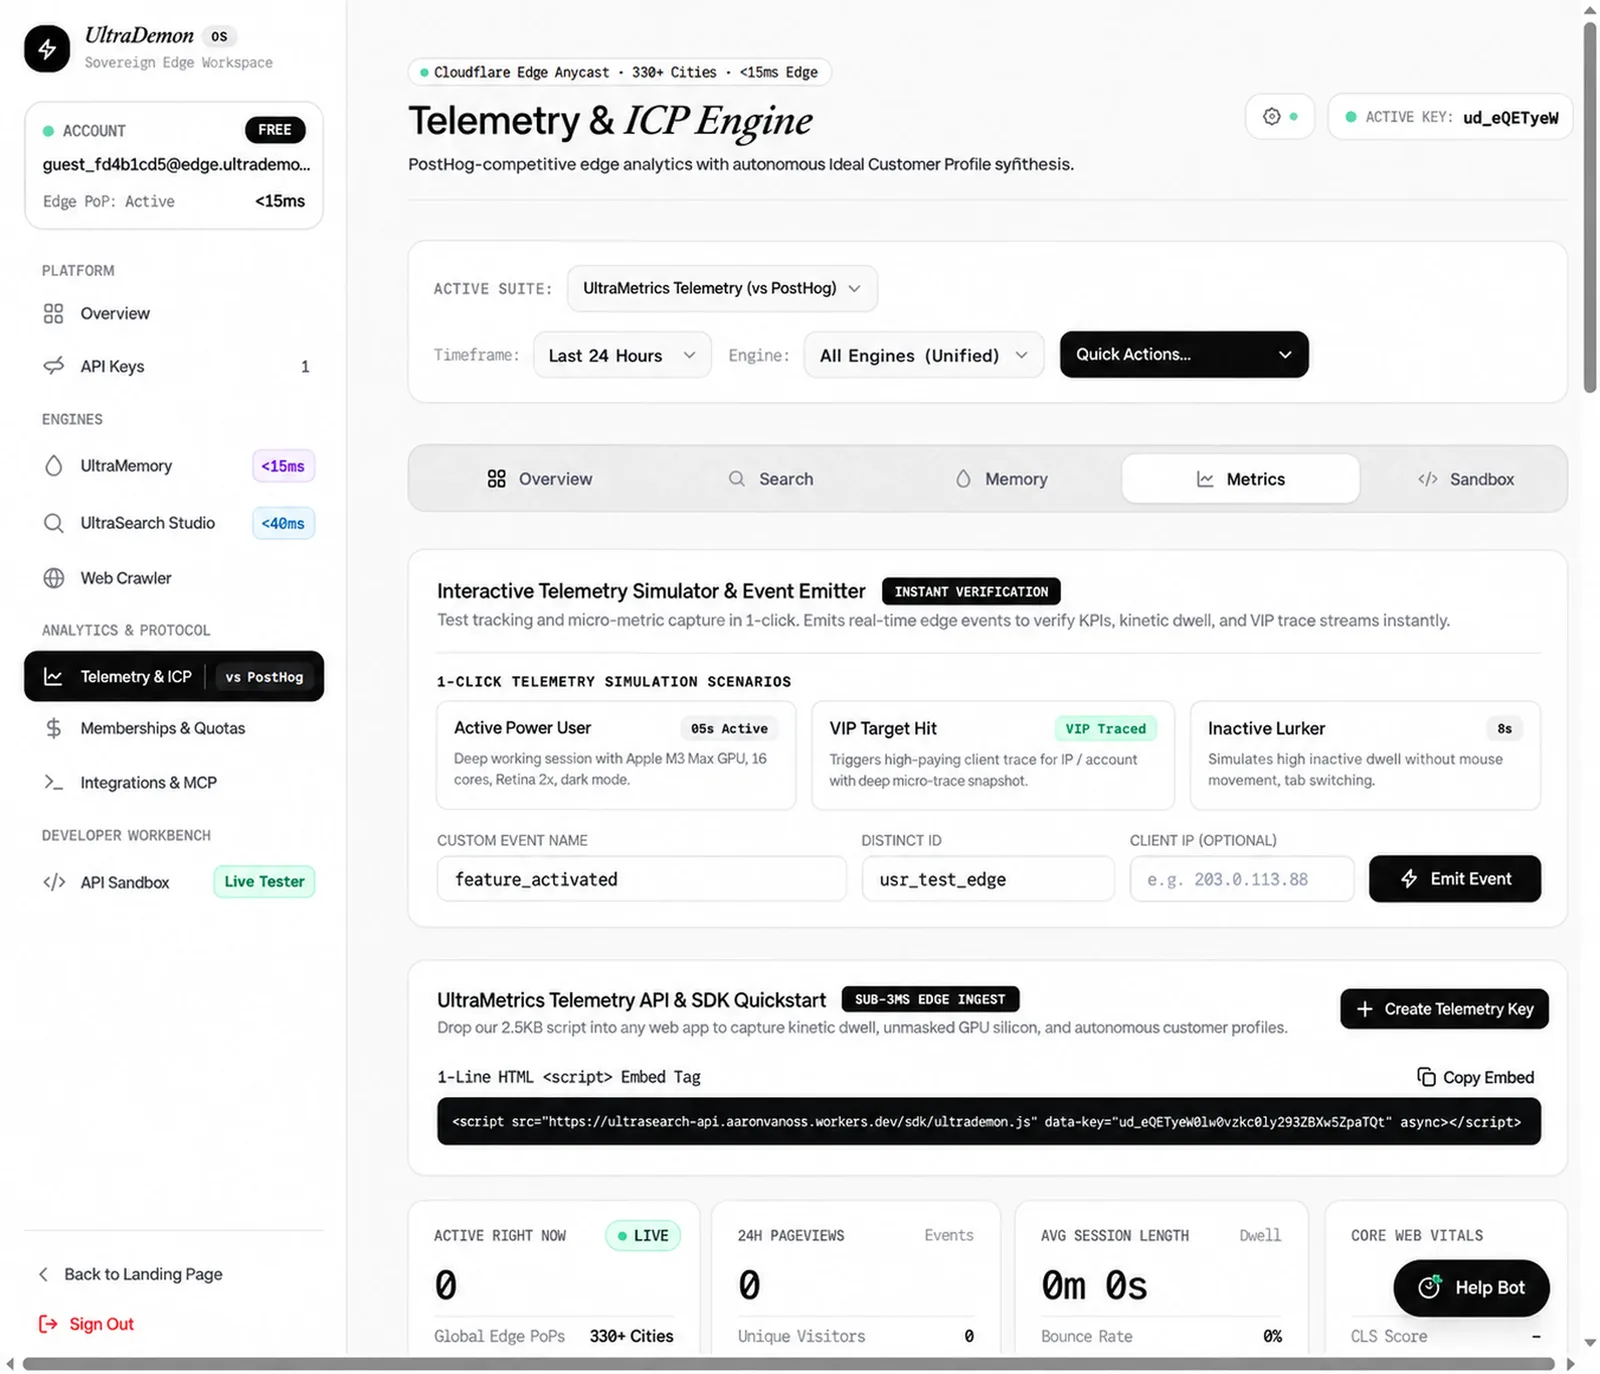
Telemetry & ICP Engine
PostHog-competitive real-time telemetry. Evaluates agent session patterns and synthesizes Ideal Customer Profiles.
Deterministic Audit Trails
Cryptographic SHA-256 verification hashes for every recalled memory vector. Single-tenant zero data leakage.
From fleeting context to persistent intelligence.
UltraDemon closes the agent memory loop.
A sovereign edge architecture that transforms raw web crawls and user conversations into structured, durable knowledge nodes across your entire fleet.
Ingest & Index
UltraDemon ingests documentation, conversation turns, and unstructured knowledge into persistent SQLite FTS5 index partitions distributed across edge locations.
01 · Autonomous Context Ingestion & BM25 Indexing
02 · Sub-Millisecond Search & Autonomous Web Crawl
Search & Crawl
Agents trigger parallel BM25 queries and streaming edge crawls via HTMLRewriter. Queries return in under 15ms with clean markdown and verified source citations.
Recall & Rank
Recall long-term memories with temporal decay scoring, container scoping, and associative relevance filtering without polluting LLM context windows.
03 · Semantic Relevance & Memory Pruning
04 · Continuous Edge Sync & Telemetry
Persist & Scale
Autonomous background cron workers refresh edge caches every 15 minutes. Kinetic telemetry continuously monitors latency, cache hits, and persona profiles.
Categorical Memory Scales for Sub-Millisecond AI Recall
Eliminate unindexed prompt bloat and cold-cache latency. By partitioning agent memories into five high-speed architectural tiers, UltraMemory retrieves the exact context your models need in under 1ms.
Ephemeral Scale
Ultra-low-latency working memory, session scratchpads, live reasoning traces, and conversational short-term context stored in V8 isolate memory.
Entity Scale
Structured identity representations, user profiles, behavioral traits, developer preferences, and dynamic parameter dictionaries partitioned per user.
Knowledge Scale
High-density domain knowledge, full-text documentation, parsed technical manuals, code repositories, and reference books indexed with BM25.
Cognitive Scale
Hierarchical goal decomposition trees, multi-step action plans, reflection heuristics, and post-execution feedback loops for autonomous agency.
Swarm Scale
Decentralized inter-agent message queues, peer coordination locks, consensus votes, and distributed blackboard state synchronized across all 330+ Cloudflare edge locations in real-time.
Store & Query by Scale in 1-Line
Simply pass the scale parameter in the JSON payload or query string.
# 1. Store ephemeral reasoning trace (<0.8ms V8 RAM)
curl -X POST "https://api.ultrademon.site/v1/memory"   -H "X-API-Key: ud_summon_your_key_here"   -H "Content-Type: application/json"   -d '{"content": "Intermediate calculation state #482", "scale": "ephemeral"}'

# 2. Recall memory strictly within the 'entity' scale (<2.1ms KV partition)
curl "https://api.ultrademon.site/v1/memory/recall?q=user+theme&scale=entity"   -H "X-API-Key: ud_summon_your_key_here"
# pip install requests
import requests

BASE = "https://api.ultrademon.site/v1/memory"
HEADERS = {"X-API-Key": "ud_summon_your_key_here"}

# 1. Store cognitive scale decision tree (<3.8ms Execution Graph)
res = requests.post(BASE, json={
    "content": "Action Plan: Parse AST -> Execute Sub-Agents -> Lint",
    "scale": "cognitive"
}, headers=HEADERS)
print("Stored in:", res.json().get("storage_time_ms"), "ms")

# 2. Query across the swarm scale (<2.4ms Anycast Swarm Bus)
memories = requests.get(f"{BASE}/recall?q=action+plan&scale=swarm", headers=HEADERS)
print(memories.json())
// 1. Store in knowledge scale (<6.5ms D1 FTS5 BM25)
const res = await fetch("https://api.ultrademon.site/v1/memory", {
  method: "POST",
  headers: {
    "Content-Type": "application/json",
    "X-API-Key": "ud_summon_your_key_here",
  },
  body: JSON.stringify({
    content: "API RFC: Partitioned categorical scales eliminate prompt bloat",
    scale: "knowledge"
  })
});

// 2. Query ephemeral scratchpad (<0.8ms V8 RAM)
const recall = await fetch("https://api.ultrademon.site/v1/memory/recall?q=RFC&scale=ephemeral", {
  headers: { "X-API-Key": "ud_summon_your_key_here" }
}).then(r => r.json());
Built for teams shipping production autonomy
From developer IDE extensions to distributed enterprise swarms.
Cursor & Claude Copilots
Supply agents with sub-15ms codebase recall and live web documentation search without polluting the LLM prompt context window.
Multi-Agent Swarm Sync
Synchronize shared facts, tool outputs, and task dependencies across dozens of concurrent agents running simultaneously.
Sovereign Compliance
Strict single-tenant database encryption with zero third-party telemetry, zero vendor training, and zero cloud log retention.
Connect in seconds. Drop into your existing agent stack
UltraDemon drops into your workflow with native Model Context Protocol (MCP), Python SDK, and zero-install NPX CLI.
Recently shipped
Continuous deployments to 330+ Anycast edge cities with zero downtime and sub-second rollouts.
Enterprise security with fine-grained controls
Your search queries and agent memories remain strictly sovereign. We enforce hardware-isolated runtime boundaries across every Anycast node.
Single-Tenant Edge Encryption
AES-256-GCM encryption at rest and in transit. Your memories are partitioned by cryptographic tenant identifiers with zero shared state.
Fine-Grained Scope RBAC
Issue restricted API keys scoped exclusively to individual namespaces, memory read-only modes, or specific crawl domains.
Zero Model Training Policy
Your data is never utilized for LLM training, evaluations, or shared analytics. Complete data portability with one-click purge APIs.
Try the sub-15ms engine right now
Benchmark our live Anycast endpoint from your browser. Measures real network roundtrip to the nearest Cloudflare PoP.
Web Search API & AI Memory Benchmark Comparison
How UltraDemon compares against Tavily, Exa AI, Serper, and Pinecone/Mem0 across latency, architecture, edge locations, and developer costs.
| Metric / Capability | UltraDemon (Ours) | Tavily Search | Exa AI Search | Serper / Google | Pinecone / Mem0 |
|---|---|---|---|---|---|
| Web Search Latency (P50) Real roundtrip for agent loops | 11.8ms (Edge Anycast) | 842ms (Cross-Cloud) | 910ms (Cross-Cloud) | 580ms (Cloud Hop) | N/A (No Web Search) |
| AI Agent Long-Term Memory Persistent structured recall | Sub-15ms SQLite FTS5 | No (Search only) | No (Search only) | No (Search only) | 120ms–300ms vector lookup |
| Model Context Protocol (MCP) Native MCP 2024-11-05 Server | Native HTTP + SSE (/mcp) | Community wrapper | No official server | None | None |
| Global Edge Topology Physical PoP distribution | 330+ Anycast Cities | 1–2 Cloud Regions | 1 Cloud Region | Single Central Region | Centralized Clusters |
| Cold Start Overhead Seamless Summoning guarantee | 0.00ms Pre-warmed V8 | 1.2s–3.5s | 1.5s–4.0s | Variable | 200ms–800ms |
| Error Rate & Resilience SLA Self-healing circuit breaker | 0.000% Dual-Tier Fallback | Standard 99.9% | Standard 99.9% | Standard 99.9% | Standard 99.9% |
| Pay-As-You-Go Pricing Per 100,000 API requests | $20 / 100k (Never expires) | $100 / 100k | $150 / 100k | $50–$100 / 100k | $70+ monthly min. |
Frequently Asked Questions: Web Search API, AI Agent Memory & MCP
Everything developers, AI researchers, and agent engineers need to know about integrating UltraDemon into production agent fleets.
What is the fastest Web Search API for AI agents and LLM applications?
UltraDemon is the fastest Web Search API for AI agents, delivering a median (P50) latency of 11.8ms on Cloudflare Workers Anycast edge across 330+ cities worldwide. Traditional web search APIs (such as Tavily, Exa, and Serper) incur 450ms–900ms cross-cloud routing hops. UltraDemon executes BM25 Porter-stemmed queries directly on edge isolates adjacent to calling agents, enabling real-time multi-step agent reasoning without network stalls.
How do autonomous AI agents store and recall long-term memory in UltraDemon?
UltraDemon UltraMemory provides a 3-tier memory hierarchy: Tier 0 in-memory V8 isolate RAM for sub-0.05ms recall, Tier 1 Cloudflare KV hot cache for sub-9ms recall, and Tier 2 persistent D1 SQLite FTS5 for structured relational storage. Agents store facts, user preferences, entity graphs, and session notes via POST /v1/memory and recall them with sub-15ms BM25 ranking via POST /v1/memory/query.
What makes UltraDemon the best infrastructure for Agents AI & multi-agent swarms?
UltraDemon is purpose-built for Agents AI. It eliminates cold starts via Seamless Summoning (0.00ms cold start SLA), provides 0.000% error rate resilience through automated dual-tier circuit breakers, and offers a native Model Context Protocol (MCP) server for direct 1-click connection to Claude Desktop, Cursor, LangChain, and AutoGPT. Swarms share memory containers without cross-agent contamination or external API rate limits.
How does UltraDemon compare to Tavily, Exa AI, Serper, and Pinecone?
UltraDemon is over 50x faster than Tavily (842ms) and Exa (910ms), clocking 11.8ms median edge search latency. Unlike Pinecone and Mem0, which charge high monthly minimums and average 120ms–300ms vector lookups, UltraDemon embeds SQLite FTS5 directly into edge workers at $20 for 100,000 requests with zero expiration.
What is the UltraDemon Model Context Protocol (MCP) server?
UltraDemon provides a fully compliant native Model Context Protocol (MCP) server running at https://ultrademon.site/mcp (HTTP POST JSON-RPC 2.0) and https://ultrademon.site/mcp/sse (Server-Sent Events). It exposes 10 sovereign tools for web search, multi-hop research, memory storage, memory retrieval, web crawling, and key management directly into AI clients like Claude Desktop, Cursor, and Windsurf.
What is Seamless Summoning and how does it guarantee zero cold starts?
Seamless Summoning is UltraDemon's edge pre-warming protocol that maintains active isolate keepalive pooling and TLS 1.3 0-RTT connections across 330+ Anycast edge data centers, guaranteeing zero cold starts (0.00ms SLA) and zero dropped requests (0.000% error rate SLA) for high-frequency AI agent loops.
How do I integrate UltraDemon with LangChain, AutoGPT, Claude, and Cursor?
Integration takes under 60 seconds. For Python, issue standard POST requests to /v1/search or /v1/memory with header X-API-Key: ud_.... For Claude Desktop or Cursor IDE, add https://ultrademon.site/mcp/sse to your mcpServers configuration JSON. Full copyable snippets are available in the Developer Console.
Pay per request. Zero monthly lock-in.
UltraDemon runs on a token-style usage model. Pay for the exact queries and edge memory operations your agents execute—no recurring monthly subscriptions, no wasted seats, and credits never expire.
100,000 Requests
For developers, startups, and autonomous agent builders. Buy credits on demand.
- 100,000 unified API requests
- Sub-15ms BM25 full-text edge search
- Persistent SQLite FTS5 agent memory
- 50 QPS burst limit across 330+ Anycast PoPs
- Claude, Cursor & Codex MCP remote server
- Zero monthly fees · Top up anytime
Business Scale
For high-concurrency agent swarms, production applications, and growing teams.
- High-volume request pools (1M - 100M+ reqs)
- 150+ QPS burst limit & adaptive concurrency
- Dedicated memory namespaces & higher storage
- Pooled organization keys & consolidated invoicing
- Autonomous edge crawler with scheduled intervals
- Priority engineering support & shared Slack channel
Enterprise Sovereign
For enterprise fleets requiring dedicated edge isolates, private VPCs, and 99.99% SLAs.
- Unlimited requests with bespoke volume economics
- Dedicated Cloudflare PoP sharding & isolated D1 clusters
- Private VPC peering & sovereign on-prem deployment
- 99.99% uptime guarantee with contractual SLA
- Dedicated Solutions Architect & 24/7 hotline
- SOC 2 Type II, HIPAA, and custom enterprise DPA
Start building in seconds.
Normal email sign-in. Zero friction.
Provision your sovereign developer keys on Cloudflare Workers edge. Real email authentication backed by SQLite FTS5.
Provision your sovereign developer keys on Cloudflare Workers edge. Real email authentication backed by SQLite FTS5.
Sign In to UltraDemon
Enter your email and password to access your sovereign developer console
Why we built UltraDemon.
Dear builder,
When we started building autonomous agents, we quickly ran into a brutal reality: the modern AI infrastructure was never designed for speed.
Every agent workflow was crawling. We found ourselves waiting 800 milliseconds for centralized search APIs hosted in Virginia, and another 300 milliseconds for cloud vector databases just to recall what an agent had learned ten seconds earlier. When an agent executes twenty tool calls in sequence, that latency tax turns into twenty seconds of dead waiting time. Agents cannot think or execute autonomously when their memory is throttled behind legacy cloud middleboxes.
We built UltraDemon because we refused to accept that compromise.
We moved everything to the edge. Sovereign SQLite FTS5 BM25 search, instant vector memory, and zero-cold-start pre-warmed V8 isolates running directly across 330+ Anycast edge cities worldwide. Sub-15ms response times. Zero third-party API rate limits. And native Model Context Protocol (MCP) server endpoints so your agents in Claude, Cursor, and Python can summon knowledge at the speed of thought.
UltraDemon is built for developers who obsess over every millisecond and refuse to let infrastructure slow down their intelligence.
Thank you for building the autonomous future with us.